Quick answer
Keep the information, prompts, evaluation examples and records you need in usable, exportable forms. Choose models for the task, test replacements and inspect the whole data flow. Local deployment can be an option; it does not establish quality, lower total cost or legal compliance on its own.
Have a task to simplify?
Explore AI PartnershipPick an AI tool you use today and imagine replacing it. What happens to your data, prompts, evaluations and working history? That question matters even if you have no plan to change providers.
My position is simple: treat the knowledge and evidence your team builds as assets you can retain and understand. Choose the model for the work, and prepare for that choice to change.
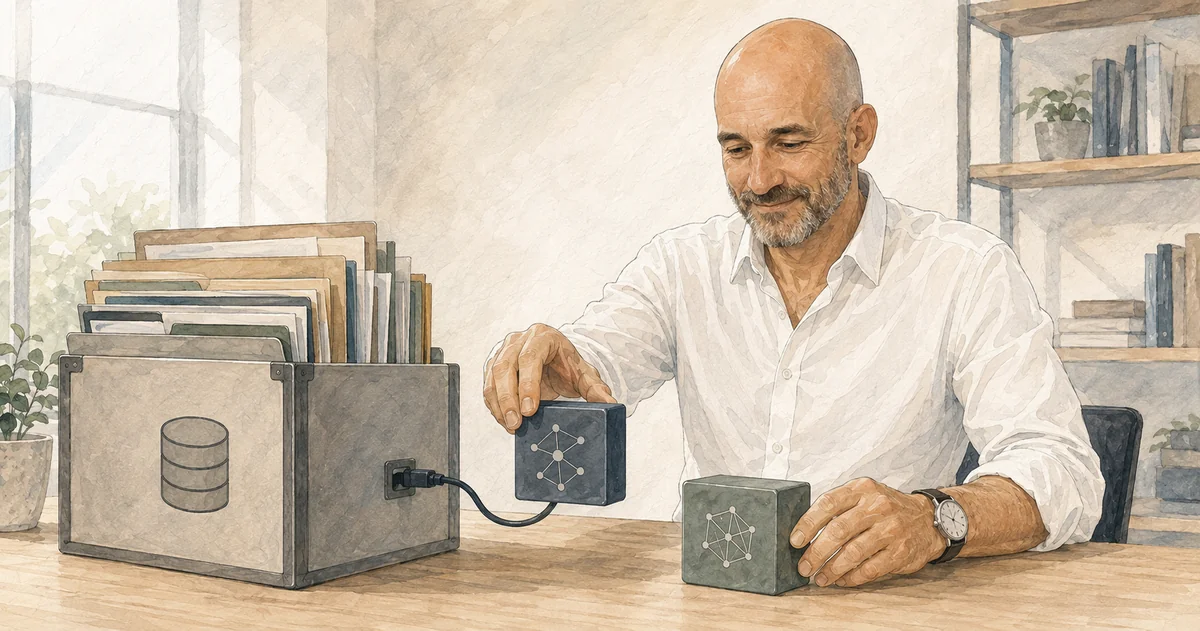
The model is the consumable
Calling the model a consumable is an operating principle, not a prediction that all models are interchangeable. Quality, cost, latency, licence terms and integrations can make one model appropriate for a task and another unsuitable. Compare them against the same examples instead of assuming a newer release is a drop-in replacement.
What deserves continuity is your data. Your prompt library. Your evaluation sets. Your customer history. The labelled examples your team built. The record of important decisions a tool made on your behalf. Those assets help you test the next system against work you already understand. The model is the engine; your data gives it a route and a purpose.
When records, business rules and integrations become tightly embedded in one platform, switching can require substantial reconstruction. AI does not remove that dependency automatically. Export formats, access rights, licences and the ability to reproduce the workflow still matter.
Bring the model to your data
Running a suitable model near your data is one option. Ollama and LM Studio support local inference. LM Studio documents offline use once the required model files are downloaded; Ollama also has cloud features and documents how to disable them. LM Studio’s offline documentation and Ollama’s local-only instructions describe those configurations.
“Open-weight” does not establish every permission to use or redistribute a model. Check the particular licence. Hardware requirements depend on the model, quantization, context and workload; the fact that a model starts on a laptop does not establish that it meets your quality or response-time requirements.
A smaller local model may be useful for a bounded task. Test it on representative examples and count review time, hardware, maintenance and operating costs alongside any API savings. I would not promise the same result for a fraction of the cost without that comparison.
Local inference also does not make every connected component local. Check document storage, retrieval services, plugins, logs and backups. The useful question is where each part of the workflow sends information, not simply whether the application is installed on your machine.
The governance question in Quebec
For a Quebec business subject to the private-sector privacy law, section 12.1 addresses decisions based exclusively on automated processing of personal information. A model that drafts text does not automatically fall into that category. Examine what the system does and who decides. See section 12.1.
Data location raises another question. The CAI explains that a PIA is required before communicating personal information to an entity outside Quebec or entrusting an outside person or organization with specified handling of that information on your behalf. Its guidance sets out these situations, in French. This is a separate analysis from whether a decision is exclusively automated.
I would map the information, access, hosting and supplier responsibilities before connecting a real process. “Local” and “cloud” are architecture choices; neither label by itself establishes legal compliance. The operating model matters as much as the tool choice.
Separate portable from proprietary
Keep exportable copies of the assets you are entitled to retain: prompts, evaluation examples, approved reference material and necessary activity records. Document their meaning and version them. Apply the appropriate access and retention rules; portability does not mean keeping personal information indefinitely.
Record dependencies too. Provider-specific tool calls, retrieval indexes, model settings and plugins may need adaptation or rebuilding. Before switching, rerun your quality examples, check access and data flows, test integrations and confirm who approves the change. Good documentation can reduce migration work; it does not turn every migration into a configuration change.
ISO/IEC 42001 offers a management framework for responsibilities, risks and ongoing review. Separately, OSFI’s final E-23 model-risk guideline takes effect for federally regulated financial institutions on May 1, 2027. OSFI’s publication gives the date and scope. These references do not impose the same obligations on every business.
A practical test is to take one workflow and ask: can we retrieve the necessary records, understand the decisions and test an alternative without rebuilding our knowledge from memory? That is the value I want to protect. For the knowledge layer, see how a company knowledge base can support the work.
Sources
- LM Studio: offline operation
- Ollama: FAQ and local-only configuration
- Quebec private-sector privacy law and CAI: privacy responsibilities and PIAs, in French
- ISO: ISO/IEC 42001 explained
- OSFI: final E-23 publication letter and May 2027 effective date
Video version
A video version is also available: watch Own the Data. Rent the Model. on YouTube.
Sources and scope. Official references are linked beside the relevant passages. Adapt the proposed working methods to your tasks, information and responsibilities.
Work on one priority at a time
Explore support built around your real work, your tools and your checkpoints.
Explore AI Partnership